Like most developers, my initial experience with LLMs was pretty straightforward. I made API calls, experimented with prompts, tweaked instructions, and tried to get better responses from the model.
Most of my focus was on the application side: how to integrate an LLM, structure prompts, and use the responses to build useful features. The model itself was essentially a black box, and honestly, that was fine. I could get things done without understanding what was happening inside.
Recently, I started exploring how to host private LLMs. That got me curious about what happens beyond the API call. How does a model actually run? Why does it need so much memory? Why does generating a response take time? And what exactly does inference mean?
I kept coming across the term, but it seemed to mean slightly different things depending on the context.
This post is my attempt to make sense of what I’ve learned so far. I’m writing it for developers who, like me, have been using AI APIs and experimenting with prompts but haven’t spent much time looking under the hood.
What happens when you call an LLM API?
Imagine you’re building a web application and want to add an AI assistant. You send a prompt to an API, receive a response, and display it in your UI.
The implementation might look something like this:
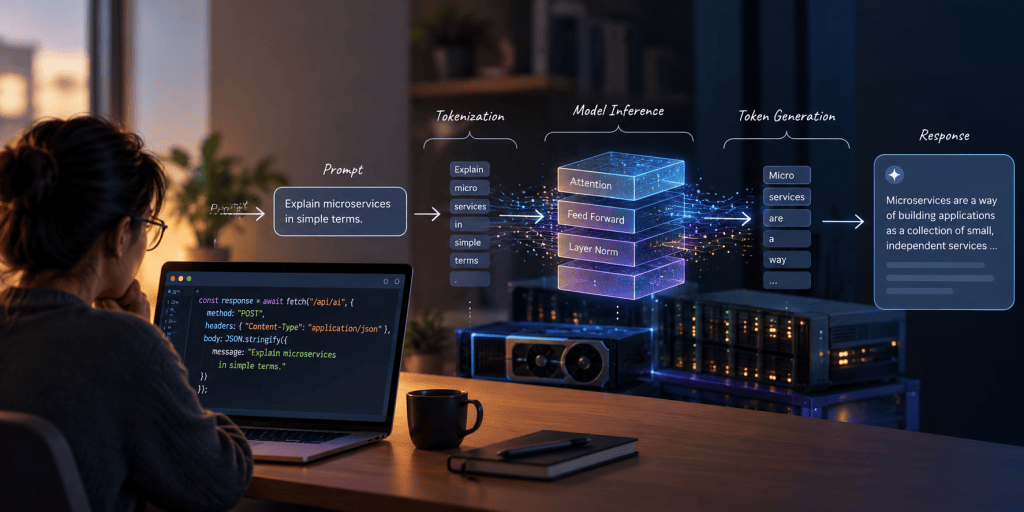
const response = await fetch("/api/ai", { method: "POST", headers: { "Content-Type": "application/json" }, body: JSON.stringify({ message: "Explain microservices in simple terms." })});
Your application sends a request, the AI generates an answer, and your UI displays it. From an application developer’s perspective, this looks no different from calling any other external service.
But something interesting happens between the request and the response.
The model processes your input, performs a series of computations, predicts what text should come next, and repeats that process until it has generated an answer.
This process is called inference.
What exactly is an AI model?
Before getting into inference, I found it helpful to understand what we’re actually running.
An AI model contains learned parameters, commonly called weights. These are numerical values adjusted during training so that the model learns patterns in language, code, and other data.
Take Llama 3.1 8B, for example. It has approximately 8 billion parameters. If each parameter is stored using 16 bits, the weights alone require roughly 16 GB of memory.
That’s a surprisingly large amount of memory for something that can be accessed through a relatively simple API.
But here’s the interesting part: the model isn’t a conventional database of questions and answers. When you ask it to explain microservices, it doesn’t simply look up a stored explanation. It uses patterns learned during training, together with your input, to generate a response.
The model’s learned weights are generally fixed during inference. The computations performed using those weights are what produce the response.
One important distinction: the weights aren’t the entire running system. The model also needs software to execute its computations and memory for intermediate data and other runtime state.
Training vs. inference
This was the first distinction I needed to understand.
Training is how a model learns. Inference is how we use it.
During training, the model’s weights are adjusted using data. During inference, the trained model uses those weights to generate an output for a new input.
| Training | Inference | |
|---|---|---|
| Purpose | Learn patterns from data | Generate an output |
| What happens to weights? | They are updated | They are normally unchanged |
| When does it happen? | During training or fine-tuning | Whenever the model processes a request |
| Cost | Training compute and infrastructure | Ongoing cost of serving requests |
I initially thought of training as the expensive part and inference as simply using the result. But inference has its own costs.
Training is an investment in creating a model. Inference is the recurring work required to serve it.
When you use a hosted LLM API, the provider bears the cost of running the model and typically charges you according to its pricing model. If you host the model yourself, you take on the infrastructure and operating costs.
As usage grows, inference can become a significant expense. For a heavily used product, the cumulative cost of serving requests can even exceed the original training cost.
Running a model: one token at a time
So, what actually happens when the model generates a response?
The first step is tokenization. The prompt is broken into smaller units called tokens. A token might represent a whole word, part of a word, punctuation, or another text fragment.
The model processes these tokens and generates a response one token at a time. It predicts the next token based on the context, adds that token to the sequence, and repeats the process.
For example, given the input:
The capital of France is
The model might predict Paris as the next token. It then uses the expanded sequence to predict what comes next.
This continues until the model reaches a stopping condition, such as an end-of-sequence token or an output limit.
So a response containing 500 tokens involves repeatedly generating tokens, rather than producing the entire response in a single step.
That explains one thing I’ve noticed when using AI: longer responses generally take longer to generate. The model has more tokens to produce, and each additional token requires more computation.
Inference means more than generating a response
As I explored the topic further, I noticed that inference is used in different contexts.
Sometimes people use it to describe the act of running a trained model. Other times, they’re talking about token generation, GPU performance, or the infrastructure needed to serve a large number of requests.
I found it useful to think about inference at four levels:
| Level | What it refers to |
|---|---|
| Lifecycle | Using a trained model rather than training it |
| Model | Processing input and generating output tokens |
| Hardware | The computation and memory movement needed to run the model |
| Infrastructure | Serving multiple requests efficiently and reliably |
These are different perspectives on the same process.
For example, when someone talks about inference speed, they might mean how quickly a model generates tokens. When an engineering team talks about inference costs, they might mean the cost of serving thousands of requests across their infrastructure.
Understanding the context makes discussions about inference much easier to follow.
Running a model locally is one thing. Running it in production is another.
Getting a model running locally isn’t necessarily difficult. With the right hardware and inference software, you can download an open-weight model, load it, and expose it through an API.
But running a model for yourself is very different from serving an application used by hundreds or thousands of people.
Once multiple users start sending requests, you need to think about memory consumption, concurrent requests, response times, hardware utilization, and operating costs.
This is where inference engineering comes in. It focuses on making model execution efficient enough to meet a product’s performance, cost, and reliability requirements.
As an application developer, I don’t necessarily need to build an inference engine myself. I can use a hosted API or an existing inference server. But understanding the underlying constraints helps me make better decisions about model selection, application latency, and cost.
Why does generating tokens require so much work?
One thing that caught my attention while exploring local models was their memory requirement.
An 8-billion-parameter model stored using 16-bit weights needs roughly 16 GB just to hold those weights. The running model also needs memory for intermediate computations, the KV cache, and other runtime data.
The KV cache is particularly interesting. During generation, the model needs information from previously processed tokens. Instead of recomputing all the attention-related information for every token, inference engines can cache and reuse key and value tensors from earlier steps.
This improves efficiency, but the cache itself consumes memory, and its size grows with the context and number of active requests.
There’s another important consideration: loading a model into memory is only part of the problem. The hardware must also move the required data and perform the computations quickly enough to generate tokens at an acceptable speed.
For large models, memory bandwidth can be a major performance bottleneck during generation.
This helps explain why two machines that can both load a model might deliver very different response speeds.
The actual performance depends on the model architecture, hardware, numerical precision, context length, and inference implementation.
How do inference systems become more efficient?
As I learned more about the subject, a few techniques kept coming up. I don’t need to implement these myself to benefit from understanding what they do.
Batching
Instead of processing every request independently, an inference engine can process multiple requests together. This allows the hardware to work more efficiently and can improve overall throughput.
The trade-off is that waiting to form a batch can add latency, so inference engines need to balance efficiency with responsiveness.
Quantization
Quantization represents model weights using fewer bits. For example, a model that uses 16-bit weights may be converted to a lower-precision representation.
This can reduce memory requirements and sometimes improve inference speed. The trade-off is that quantization can affect output quality, depending on the model and method used.
Speculative decoding
A smaller or faster model proposes tokens that a larger model verifies. When the proposed tokens are accepted, the system can generate multiple tokens with fewer sequential steps than ordinary decoding would require.
This can improve generation speed in suitable workloads, although the benefit depends on factors such as how often the proposed tokens are accepted and the overhead involved.
These techniques address different performance constraints. Together with efficient KV-cache management and scheduling, they help make inference practical at scale.
What does this mean for application developers?
After exploring these concepts, I have a better appreciation of what happens behind an LLM API call.
I started by focusing on prompts and API integration. Now I’m beginning to understand why token counts matter, why responses take time, why hosting a model requires more than just downloading its files, and why inference becomes a separate engineering challenge when traffic grows.
I don’t think every application developer needs to understand GPU kernels or build their own inference engine. But having a basic understanding of the terminology makes it easier to reason about model limits, costs, performance, and architecture.
It also helps separate the responsibilities of the model from those of the application. The model generates a response, but the application still needs to manage context, enforce business rules, validate outputs, handle failures, and decide what to do with the result.
For me, this is the next step beyond simply making AI API calls: understanding enough of what’s happening underneath to build better applications on top of it.
I’m still learning the deeper engineering aspects of inference, but this is a useful starting point for anyone in a similar position.
Training gives the model its capabilities. Inference is what puts those capabilities to work.


Leave a Reply